Filter by type:
Filter by tags:
](images/xhtoken-wechat.jpg)
spark-x2.5-4b
# Spark-X2.5
[](https://join.slack.com/t/tokenspark/shared_invite/zt-432qf8l2f-5~dLyXv8uETr0P0UuC07nw)
[](https://discord.gg/kTDE2Hg8aw)
[](https://www.youtube.com/@SparkLLM)
[](https://dev.to/sparkllm)
[](https://bsky.app/profile/sparkllm.bsky.social)
[](https://x.com/sparkllm)
[](https://www.zhihu.com/people/zhiikz7qh7m)
[](images/xhtoken-wechat.jpg)
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
## Introduction
We are introducing Spark-X2.5-4B and Spark-X2.5-1.7B, two compact, general-purpose language models designed to make capable AI more practical, efficient, and accessible. The models deliver strong performance across a broad range of everyday tasks—including conversation, writing, translation, reasoning, coding, tool use, and agentic workflows—achieving leading results among open-source models of comparable size. Spark-X2.5 combines an efficiency-oriented architecture with native context windows of up to 1M tokens, and support for more than 200 languages.
...
Repository: localaiLicense: apache-2.0
glm-5.3-flash
# GLM-5.3-Flash
👋 Join our WeChat or Discord community.
📖 Check out the GLM-5.3-Flash blog and GLM-5 Technical report.
📍 Use GLM-5.3-Flash API services on Z.ai API Platform.
## Introduction
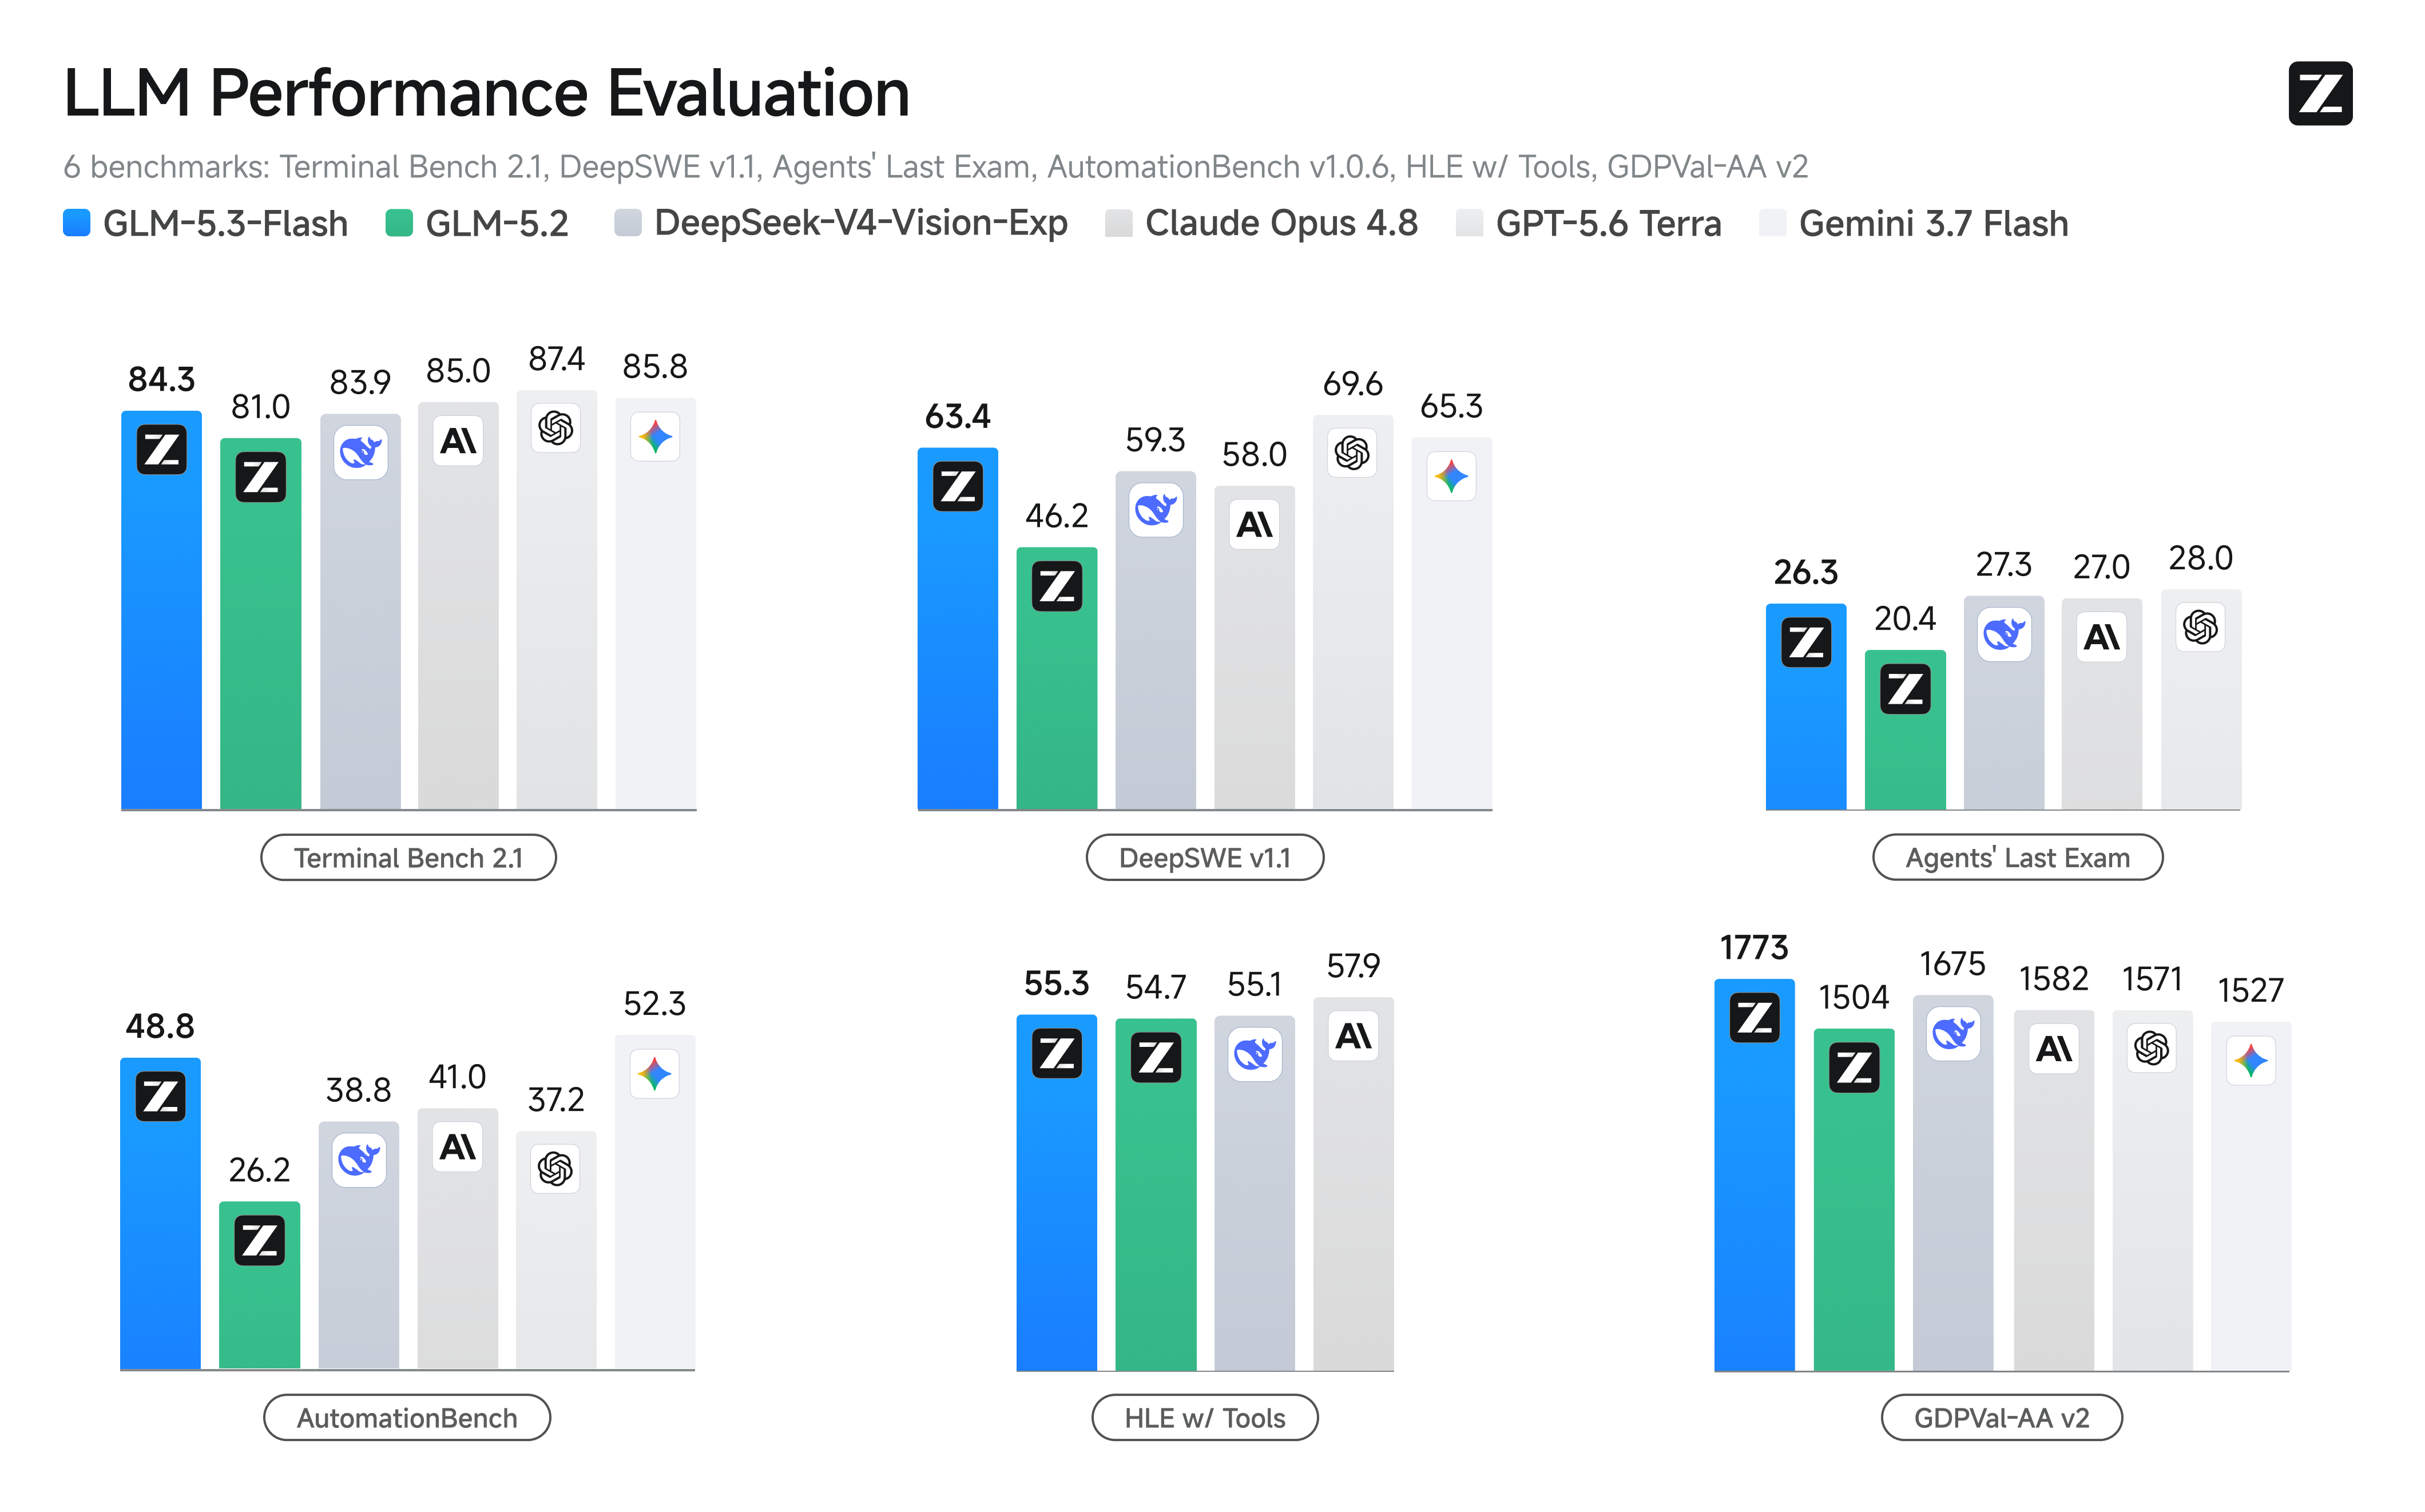
We introduce GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series. With 320B total parameters and just 18B active parameters, it outperforms GLM-5.2 across benchmarks and real-world workloads at one-tenth the price, while approaching Claude Opus 4.8 on coding and agentic benchmarks.
GLM-5.3-Flash starts from a newly trained base model, with its architecture and training recipe redesigned around capability and efficiency. For the first time in the GLM series, we introduce a hybrid architecture combining sparse and linear attention, sharply reducing long-context serving costs while preserving precise long-context capabilities. The model also adopts Manifold-Constrained Hyper-Connections (mHC) to further improve scaling efficiency. Together with our latest 30T-token multimodal pre-training corpus, these changes enable GLM-5.3-Flash to deliver more intelligence with less compute.
## Serve GLM-5.3-Flash Locally
...
Repository: localaiLicense: mit

glm-5.3-flash-q4
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts
model with 18B active parameters. It combines sparse and linear attention
for coding, agentic work, tool use, vision, and long-context tasks. This
entry uses the UD-Q4_K_XL GGUF quantization and enables the model's MTP
speculative-decoding head.
Repository: localaiLicense: mit
glm-5.3-flash-q8
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts
model with 18B active parameters. It combines sparse and linear attention
for coding, agentic work, tool use, vision, and long-context tasks. This
entry uses the higher-quality Q8_0 GGUF quantization and enables the model's
MTP speculative-decoding head.
Repository: localaiLicense: mit

qwen3.8-flash-next-q4
Qwen3.8-Flash-Next is Qwen's 125B-parameter, 6B-active experimental
vision-language mixture-of-experts model. It targets agentic coding,
reasoning, tool use, and long-context workloads with a native 262K-token
context window.
This default entry uses Unsloth's UD-Q4_K_XL GGUF and BF16 vision
projector. Linked variants offer Q8_0 and AtomicChat's smaller IQ4_XS
and Q4_K_M builds with a separate n-gram table shard.
Repository: localaiLicense: other

ling-3.0-tiny-q4
Ling-3.0-tiny is InclusionAI's MIT-licensed hybrid reasoning MoE model
with 7.9B total parameters and 1.3B active parameters per token. It
targets reasoning, coding, instruction following, and agentic tasks with
a native 131K-token context window.
This default entry uses the Q4_K_M GGUF. A higher-quality Q8_0 model is
available as a variant.
Repository: localaiLicense: mit
dirk-qwen3.8-27b-q4
Dirk is a Qwen3.8 27B vision-language model with a concise chat template
for agentic coding, reasoning, tool use, and general knowledge tasks. It
preserves the model's MTP head for speculative decoding and supports a
262K-token context window.
This default entry uses the Q4_K_XL GGUF and F16 vision projector. A
choice of Q5_K_XL, Q6_K_XL, and Q8_K_XL builds is available through variants.
Repository: localaiLicense: apache-2.0
ling-3.0-flash-iq1
Ling-3.0-flash is InclusionAI's MIT-licensed hybrid reasoning MoE model
with 124B total parameters and 5.5B active parameters per token. It targets
coding, deep research, instruction following, and agentic workflows with a
native 256K-token context window.
This default entry uses the 36.5 GB AD-IQ1_M GGUF. A higher-quality
44.7 GB AD-IQ2_XS model is available as a variant.
Repository: localaiLicense: mit
ornith-1.0-9b-q4
Ornith-1.0-9B is an MIT-licensed Qwen3.5 model from Ornith AI for
agentic coding, reasoning, repository-level software tasks, and tool use.
It supports text and image input with a context window of 262K tokens.
This default entry uses the Q4_K_M GGUF and F16 vision projector. A
higher-quality Q8_0 model is available as a variant.
Repository: localaiLicense: mit
ornith-1.5-9b-q4
Ornith-1.5-9B is an MIT-licensed Qwen3.5 model from Ornith AI for
agentic coding, reasoning, repository-level software tasks, and tool use.
It supports text and image input with a context window of 262K tokens.
This default entry uses the Q4_K_M GGUF and BF16 vision projector.
Q5_K_M, Q6_K, and Q8_0 models are available as variants.
Repository: localaiLicense: mit
ornith-1.5-35b-a3b-apex
Ornith-1.5-35B-A3B is an MIT-licensed Qwen3.5 mixture-of-experts model
from Ornith AI for agentic coding, reasoning, repository-level software
tasks, and tool use. It supports text and image input with a context window
of 262K tokens.
This default entry uses the APEX Balanced GGUF and BF16 vision projector.
Compact APEX and MTP-enabled APEX builds are available as variants.
Repository: localaiLicense: mit
ornith-1.5-9b-obliterated-q4
Ornith-1.5-9B OBLITERATED is a refusal-removed derivative for alignment
research, red teaming, coding, reasoning, and agentic tasks. Its safety
guardrails are removed, and the publisher reports some capability loss
compared with the original model.
This default entry uses the Q4_K_M GGUF and BF16 vision projector. The
linked variant uses the higher-quality Q8_0 quantization.
Repository: localaiLicense: mit
ornith-1.5-35b-a3b-q4
Ornith-1.5-35B-A3B is an MIT-licensed Qwen3.5 mixture-of-experts model
from Ornith AI for agentic coding, reasoning, repository-level software
tasks, and tool use. It activates about 3B parameters per token and
supports text and image input with a context window of 262K tokens.
This default entry uses the Q4_K_M GGUF and BF16 vision projector. A
higher-quality Q8_0 model is available as a variant.
Repository: localaiLicense: mit
ornith-1.5-397b-q4
Ornith-1.5-397B is Ornith AI's MIT-licensed flagship mixture-of-experts
model for agentic coding, reasoning, repository-level tasks, and tool use.
It supports text and image input with a context window of 262K tokens.
This default entry uses the Q4_K_M GGUF and BF16 vision projector. A
higher-quality Q8_0 model is available as a variant.
Repository: localaiLicense: mit
muse-glimmer-30b
Muse Glimmer is Meta Superintelligence Labs' Apache-2.0 dense 30B model for
autonomous agentic work, coding, tool use, long-horizon reasoning, and
multimodal understanding. It supports more than 100 languages, interleaved
text and image input through its 1.8B-parameter perception encoder, and a
131K-token context window.
This entry uses the publisher's higher-quality dynamic K-quant GGUF and
official quantized vision projector. Automatic variant selection can use
the smaller 17 GB quantization or a DFlash-accelerated build when it fits.
Repository: localaiLicense: apache-2.0
muse-glimmer-30b-17gb
Muse Glimmer's smaller 17 GB K-quant GGUF with the official quantized
perception encoder. It preserves the model's agentic, coding, tool-use,
multilingual, and image-understanding capabilities for hosts with less
memory than the dynamic quantization requires.
Repository: localaiLicense: apache-2.0
btl-4-compact
BTL-4 Compact is Bad Theory Labs' text-only 35B mixture-of-experts model
compressed into a single 9.96 GB IQ2_XXS GGUF. Around 2.1B parameters are
active per token, and the model is tuned for agentic work, tool use, coding,
and reasoning. The compact build omits the vision tower and disables the
source model's MTP layer for compatibility with stock llama.cpp.
Repository: localaiLicense: apache-2.0

deepseek-v4-flash-0731
# DeepSeek-V4-Flash-0731
Technical Report👁️
## Introduction
**DeepSeek-V4-Flash-0731** is the official release of **DeepSeek-V4-Flash**, superseding the preview version, with substantially enhanced agentic capabilities. It has the same model structure as DeepSeek-V4-Flash-DSpark, i.e. it comes with a speculative decoding module attached.
DeepSeek-V4-Flash-0731 outperforms DeepSeek-V4-Pro (Preview) on benchmarks listed below despite its far smaller activated parameter count, and is broadly competitive with the strongest proprietary models available.
Notes:
1. For the Code Agent tasks among the public benchmarks above, DeepSeek-V4-Flash-0731 is evaluated with the minimal mode of DeepSeek Harness (to be released) as the agent framework, using the `max` reasoning effort level with `temperature = 1.0, top_p = 0.95`.
2. † DSBench-FullStack is an internal full-stack development test set; DSBench-Hard is an internal test set of difficult coding-agent problems.
## Chat Template
...
Repository: localaiLicense: mit
deepseek-v4-pro-0813
DeepSeek V4 Pro 0813 is DeepSeek's MIT-licensed flagship mixture-of-experts
model for agentic coding, reasoning, and long-horizon tool use. This entry
uses Unsloth's UD-Q4_K_XL GGUF build, split into 20 shards for llama.cpp.
Repository: localaiLicense: mit
north-mini-code-1.0
North Mini Code 1.0 is Cohere Labs' Apache-2.0 sparse mixture-of-experts
coding model with 30B total parameters and 3B active parameters. It targets
code generation, agentic software engineering, terminal tasks, tool use,
and interleaved reasoning with a 256K-token context window. This entry uses
the UD-Q4_K_M GGUF quantization.
Repository: localaiLicense: apache-2.0
north-mini-code-1.0-q8
North Mini Code 1.0 is Cohere Labs' Apache-2.0 sparse mixture-of-experts
coding model with 30B total parameters and 3B active parameters. It targets
code generation, agentic software engineering, terminal tasks, tool use,
and interleaved reasoning with a 256K-token context window. This entry uses
the Q8_0 GGUF quantization.
Repository: localaiLicense: apache-2.0
Page 1