Model Gallery

161 models from 1 repositories

Filter by type:

Filter by tags:
spark-x2.5-4b
# Spark-X2.5 [](https://join.slack.com/t/tokenspark/shared_invite/zt-432qf8l2f-5~dLyXv8uETr0P0UuC07nw) [](https://discord.gg/kTDE2Hg8aw) [](https://www.youtube.com/@SparkLLM) [](https://dev.to/sparkllm) [](https://bsky.app/profile/sparkllm.bsky.social) [](https://x.com/sparkllm) [](https://www.zhihu.com/people/zhiikz7qh7m) [](images/xhtoken-wechat.jpg) > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. ## Introduction We are introducing Spark-X2.5-4B and Spark-X2.5-1.7B, two compact, general-purpose language models designed to make capable AI more practical, efficient, and accessible. The models deliver strong performance across a broad range of everyday tasks—including conversation, writing, translation, reasoning, coding, tool use, and agentic workflows—achieving leading results among open-source models of comparable size. Spark-X2.5 combines an efficiency-oriented architecture with native context windows of up to 1M tokens, and support for more than 200 languages. ...

Repository: localaiLicense: apache-2.0
glm-5.3-flash
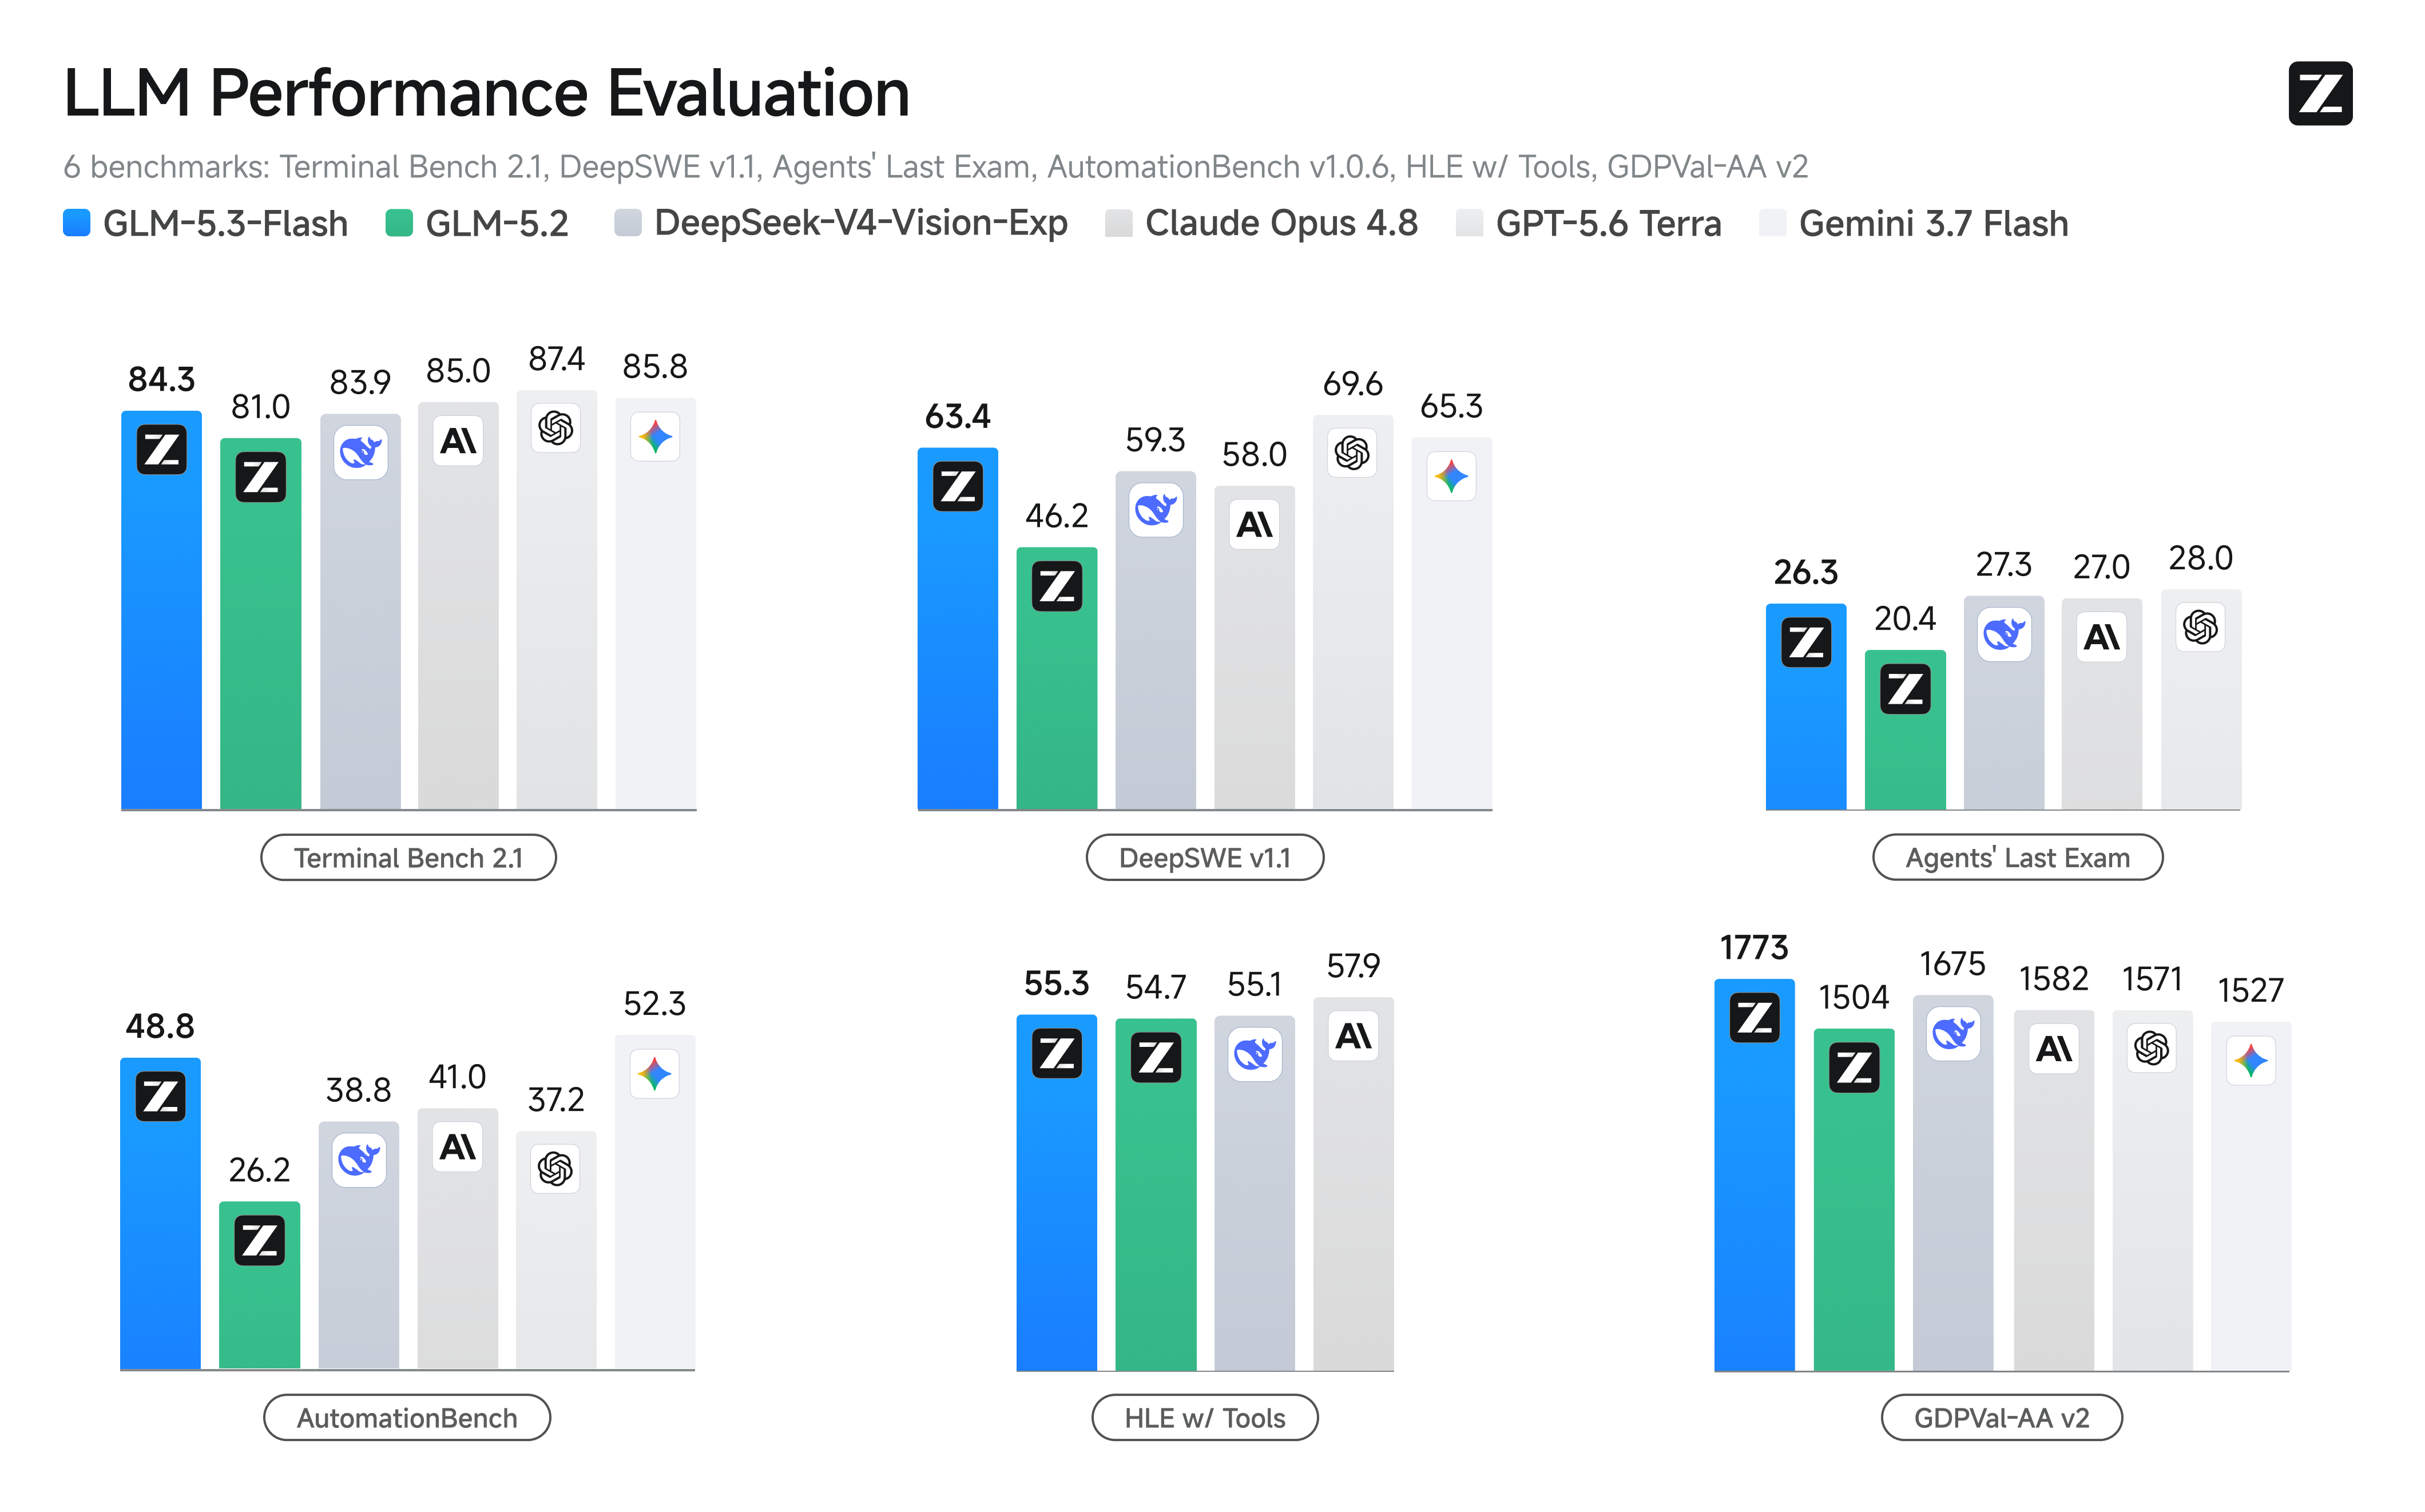
# GLM-5.3-Flash 👋 Join our WeChat or Discord community. 📖 Check out the GLM-5.3-Flash blog and GLM-5 Technical report. 📍 Use GLM-5.3-Flash API services on Z.ai API Platform. ## Introduction We introduce GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series. With 320B total parameters and just 18B active parameters, it outperforms GLM-5.2 across benchmarks and real-world workloads at one-tenth the price, while approaching Claude Opus 4.8 on coding and agentic benchmarks. GLM-5.3-Flash starts from a newly trained base model, with its architecture and training recipe redesigned around capability and efficiency. For the first time in the GLM series, we introduce a hybrid architecture combining sparse and linear attention, sharply reducing long-context serving costs while preserving precise long-context capabilities. The model also adopts Manifold-Constrained Hyper-Connections (mHC) to further improve scaling efficiency. Together with our latest 30T-token multimodal pre-training corpus, these changes enable GLM-5.3-Flash to deliver more intelligence with less compute. ## Serve GLM-5.3-Flash Locally ...

Repository: localaiLicense: mit

apodex-1.1-mini-q4-mtp
Apodex-1.1-mini with MTP speculative decoding enabled on the recommended Q4_K_M GGUF. The model carries its native MTP head, so it needs no separate draft model. The F16 vision projector supports multimodal prompts.

Repository: localaiLicense: apache-2.0

glm-5.3-flash-q4
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts model with 18B active parameters. It combines sparse and linear attention for coding, agentic work, tool use, vision, and long-context tasks. This entry uses the UD-Q4_K_XL GGUF quantization and enables the model's MTP speculative-decoding head.

Repository: localaiLicense: mit

glm-5.3-flash-q8
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts model with 18B active parameters. It combines sparse and linear attention for coding, agentic work, tool use, vision, and long-context tasks. This entry uses the higher-quality Q8_0 GGUF quantization and enables the model's MTP speculative-decoding head.

Repository: localaiLicense: mit

qwen3.8-flash-next-q4
Qwen3.8-Flash-Next is Qwen's 125B-parameter, 6B-active experimental vision-language mixture-of-experts model. It targets agentic coding, reasoning, tool use, and long-context workloads with a native 262K-token context window. This default entry uses Unsloth's UD-Q4_K_XL GGUF and BF16 vision projector. Linked variants offer Q8_0 and AtomicChat's smaller IQ4_XS and Q4_K_M builds with a separate n-gram table shard.

Repository: localaiLicense: other

ling-3.0-tiny-q4
Ling-3.0-tiny is InclusionAI's MIT-licensed hybrid reasoning MoE model with 7.9B total parameters and 1.3B active parameters per token. It targets reasoning, coding, instruction following, and agentic tasks with a native 131K-token context window. This default entry uses the Q4_K_M GGUF. A higher-quality Q8_0 model is available as a variant.

Repository: localaiLicense: mit

ling-3.0-flash-iq1
Ling-3.0-flash is InclusionAI's MIT-licensed hybrid reasoning MoE model with 124B total parameters and 5.5B active parameters per token. It targets coding, deep research, instruction following, and agentic workflows with a native 256K-token context window. This default entry uses the 36.5 GB AD-IQ1_M GGUF. A higher-quality 44.7 GB AD-IQ2_XS model is available as a variant.

Repository: localaiLicense: mit

carbon-3b-q4
Carbon-3B is Hugging Face's 3B-parameter genomic foundation model for DNA and RNA sequence generation, recovery, variant-effect prediction, and motif-perturbation analysis. It supports 32,768 tokens natively and uses a hybrid tokenizer with 6-mer DNA tokens. This default entry uses the Q4_K_M GGUF. A higher-quality Q8_0 build is available as a variant. Prefix DNA sequences with `` and use uppercase A, C, G, and T characters in groups of six.

Repository: localaiLicense: apache-2.0

carbon-8b-q4
Carbon-8B is the largest model in Hugging Face's Carbon family of genomic foundation models. It targets DNA and RNA sequence generation, recovery, variant-effect prediction, and motif-perturbation analysis with a native context length of 32,768 hybrid 6-mer DNA tokens. This default entry uses the Q4_K_M GGUF. A higher-quality Q8_0 build is available as a variant. Prefix DNA sequences with `` and use uppercase A, C, G, and T characters in groups of six.

Repository: localaiLicense: apache-2.0

ornith-1.5-35b-a3b-mtp-apex
Ornith-1.5-35B-A3B in the APEX Balanced GGUF format with native multi-token prediction enabled for speculative decoding, plus the shared BF16 vision projector.

Repository: localaiLicense: mit

ornith-1.5-35b-a3b-mtp-apex-compact
Ornith-1.5-35B-A3B in the APEX Compact GGUF format with native multi-token prediction enabled for speculative decoding, plus the shared BF16 vision projector.

Repository: localaiLicense: mit

thomson-1.0-small-q4
Thomson-1.0-Small is a 35B-parameter mixture-of-experts model with about 3B active parameters. It focuses on legal, tax, journalism, research, reasoning, tool use, and document processing. It supports text and image input with a native context window of 262K tokens. This default entry uses the Q4_K_M GGUF and BF16 vision projector. A higher-quality Q8_0 model is available as a variant.

Repository: localaiLicense: polyform-strict-1.0.0

qwen3.8-27b-q4
Qwen3.8-27B is Qwen's dense 27B vision-language model for reasoning, coding, tool use, and long-running agent tasks. It accepts text, images, and video, and it supports a native context window of 262K tokens. This default entry uses the official Q4_K_M GGUF and Q8_0 vision projector. The linked variants add MTP speculative decoding or use the higher-quality Q8_0 model.

Repository: localaiLicense: apache-2.0

qwen3.8-9b-q4
Qwen3.8-9B is Empero AI's full-parameter distillation of Qwen3.8 2.4T A95B into the dense Qwen3.5-9B architecture. It targets reasoning, mathematics, coding, instruction following, and tool use, and supports a native 262K-token context window. This default entry uses Q4_K_M weights; a higher-quality Q8_0 build is available as a variant.

Repository: localaiLicense: apache-2.0

qwen3.8-4b-q4
Qwen3.8-4B is Empero AI's full-parameter distillation of Qwen3.8 2.4T A95B into the Qwen3.5-4B architecture. It targets mathematics, reasoning, instruction following, and tool use with a native 262K-token context window. This default entry uses Q4_K_M weights; a higher-quality Q8_0 build is available as a variant.

Repository: localaiLicense: apache-2.0

qwen3.8-2b-q4
Qwen3.8-2B is Empero AI's smallest Qwen3.8 reasoning distillation. It uses the Qwen3.5-2B architecture and targets mathematics, instruction following, tool use, and edge deployment with a native 262K-token context window. This default entry uses Q4_K_M weights; a higher-quality Q8_0 build is available as a variant.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-cold-fusion-q4-mtp
Qwen3.8 27B Cold Fusion is an Apache-2.0 multimodal fine-tune for reasoning, coding, creative writing, and roleplay. This entry uses the publisher's NEO-imatrix Q4_K_M GGUF with multi-token prediction enabled. It supports vision through the shared BF16 projector and a native 256K context window.

Repository: localaiLicense: apache-2.0

qwen3.8-2b-distill-q4
Qwen3.8 2B Distill is an Apache-2.0, text-only Qwen3.5 2B fine-tune distilled from Qwen3.8 2.4T A95B reasoning traces. It targets compact reasoning, coding, instruction following, and function calling with a 262K native context window. This entry uses the balanced Q4_K_M GGUF quantization; the Q8_0 variant offers higher fidelity.

Repository: localaiLicense: apache-2.0

qwen3.8-2b-distill-q8
Qwen3.8 2B Distill in the higher-fidelity Q8_0 GGUF format. This text-only Qwen3.5 2B fine-tune targets reasoning, coding, instruction following, and function calling with a 262K native context window.

Repository: localaiLicense: apache-2.0

qwen3.8-4b-distill-q4
Qwen3.8 4B Distill is an Apache-2.0, text-only Qwen3.5 4B fine-tune distilled from Qwen3.8 2.4T A95B reasoning traces. It targets reasoning, coding, instruction following, and function calling with a 262K native context window. This entry uses the balanced Q4_K_M GGUF quantization; the Q8_0 variant offers higher fidelity.

Repository: localaiLicense: apache-2.0

Page 1