Filter by type:
Filter by tags:
qwen3.8-flash-next-uncensored
# Qwen3.8-Flash-Next
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.
> [!Tip]
> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud.
>
> In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview.
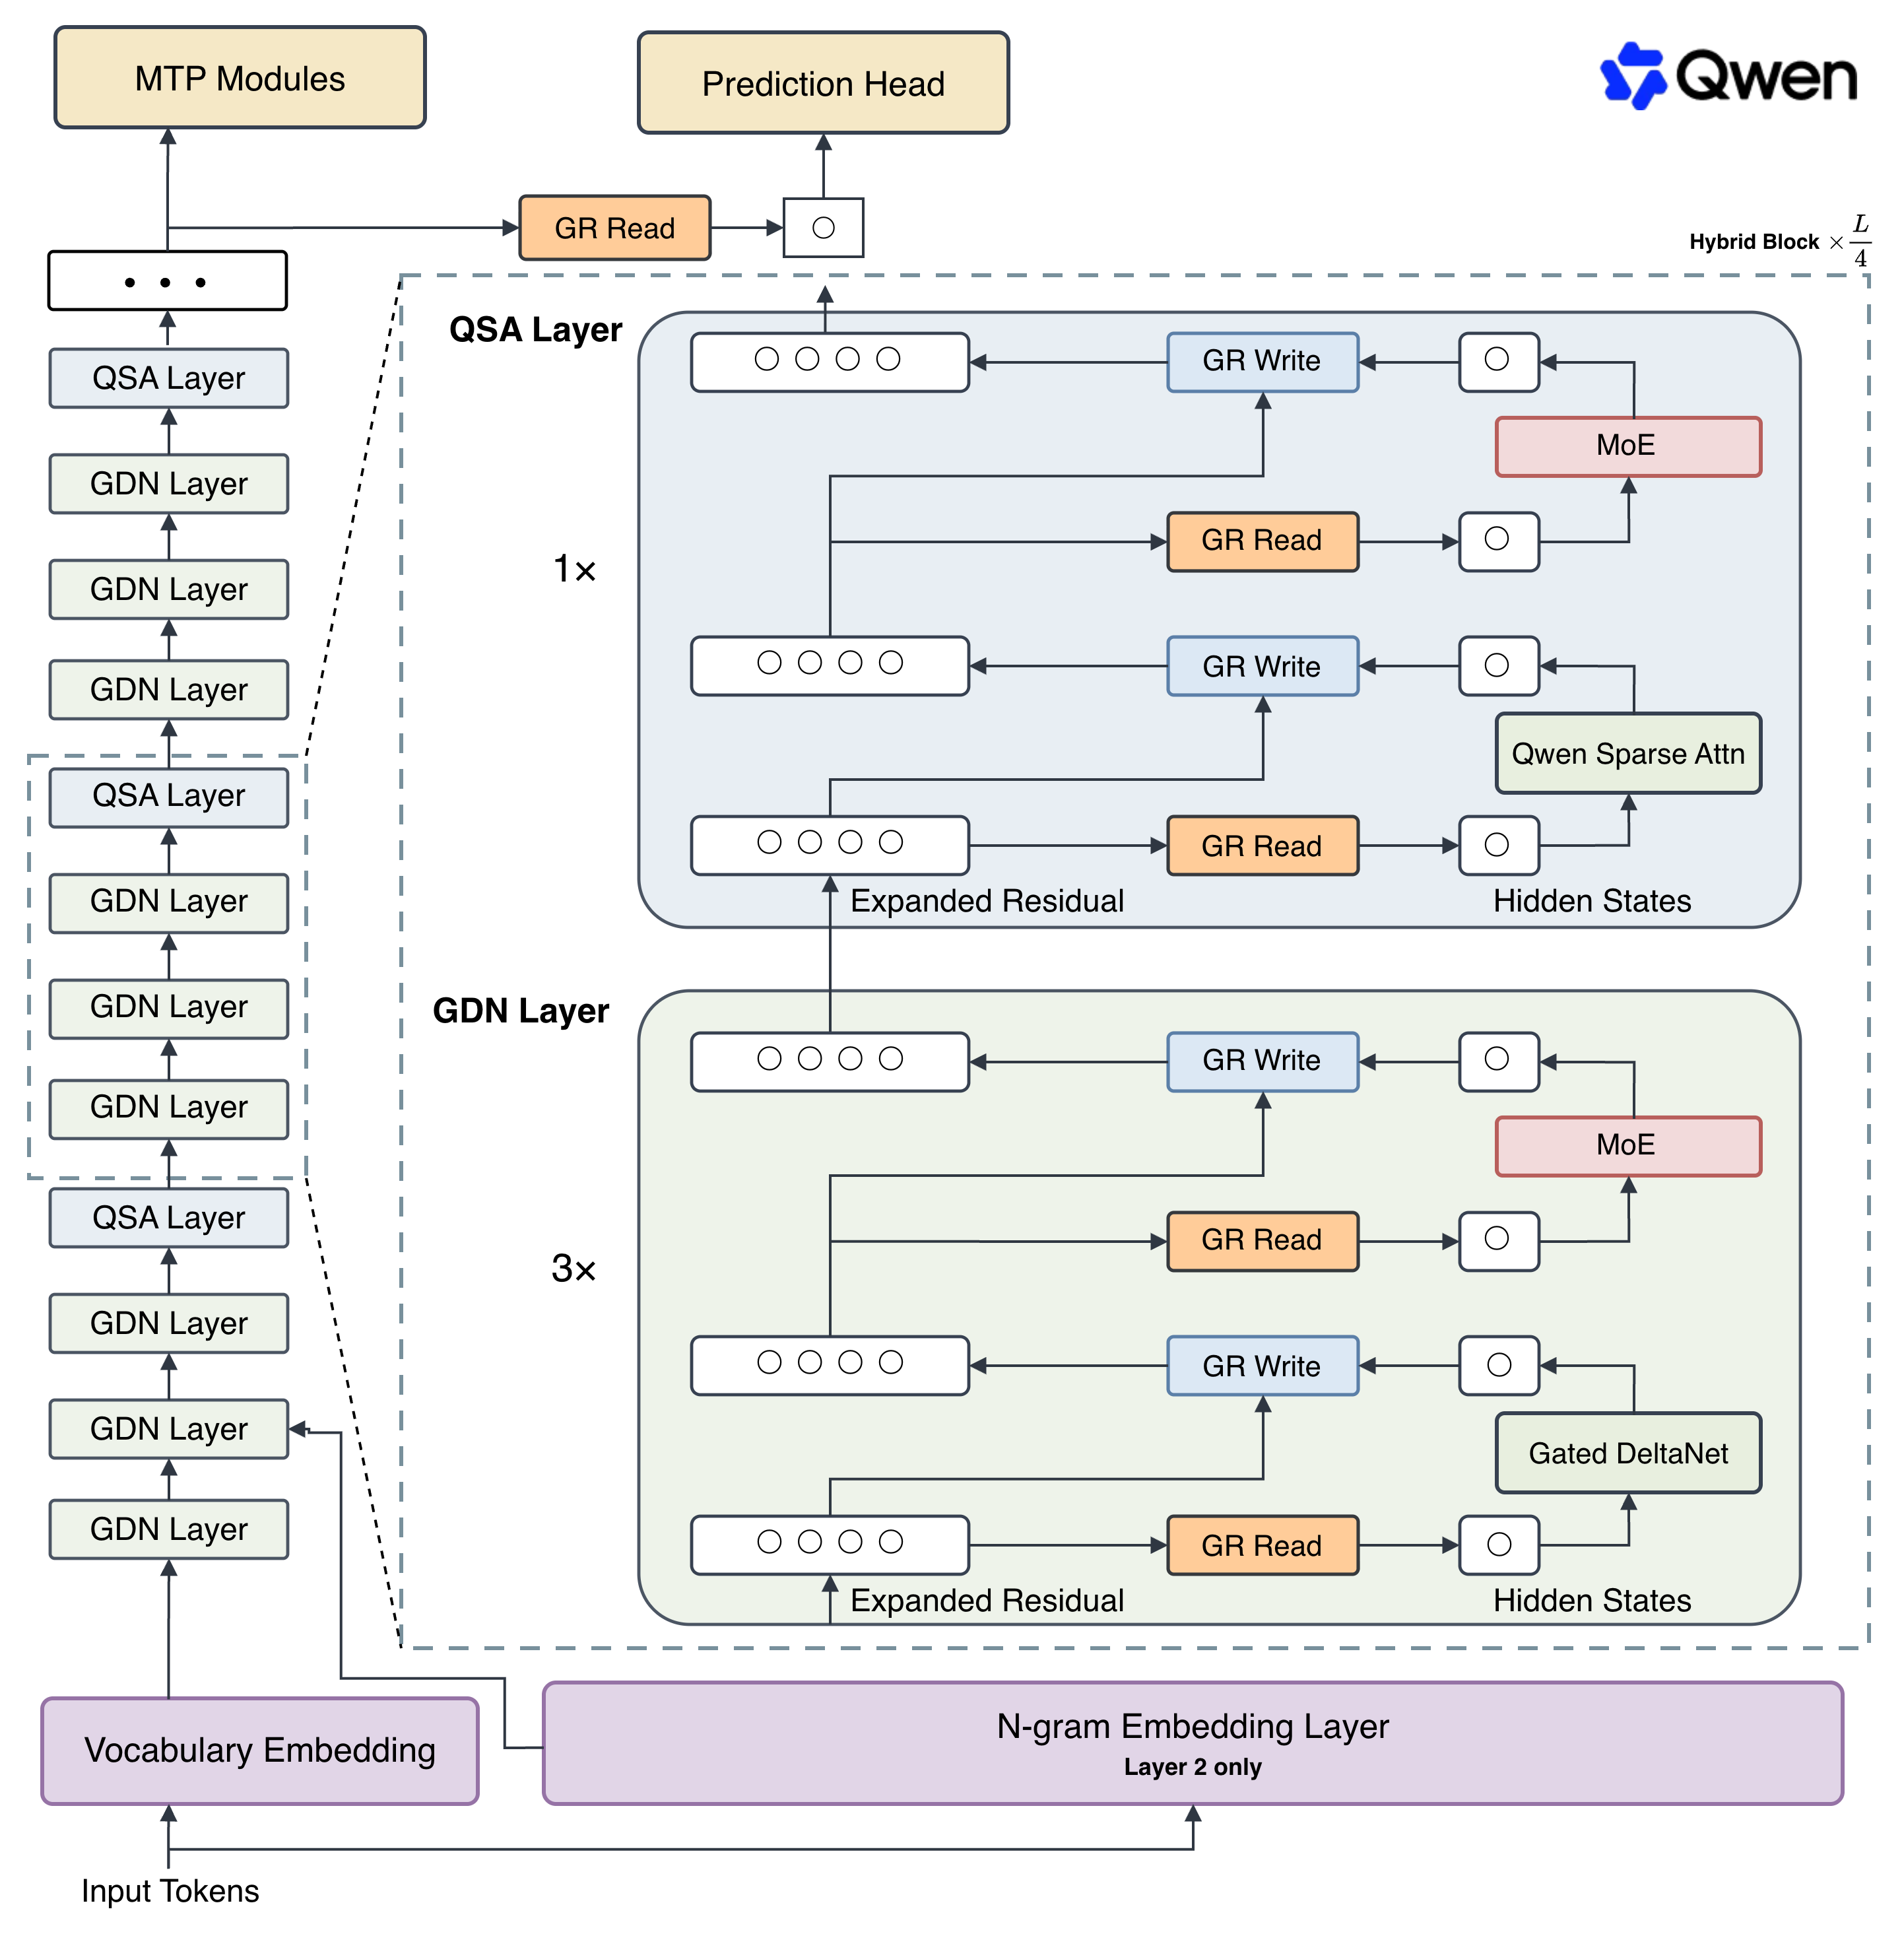
As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next.
...
Repository: localaiLicense: apache-2.0

deepseek-v4-flash-vision-exp
# DeepSeek-V4-Flash-Vision-Exp
## Introduction
We are excited to introduce **DeepSeek-V4-Flash-Vision-Exp**, our first experimental multimodal model in the DeepSeek-V4 family. It builds on the DeepSeek-V4-Flash architecture by incorporating visual modules and undergoing continued training to unlock visual understanding capabilities.
Compared to DeepSeek-V4-Flash-0731, DeepSeek-V4-Flash-Vision-Exp achieves substantial improvements on its multimodal agent capabilities, while maintaining comparable performance on text-only agent tasks.
Notes:
1. For the text agent benchmarks above, DeepSeek models are evaluated with the minimal mode of DeepSeek Harness as the agent framework, using the `max` reasoning effort level with `temperature = 1.0, top_p = 0.95`.
2. † For ApexBench and Agents' Last Exam, DeepSeek-V4-Flash-0731 ignores the multimodal elements in the input.
## Repository layout
This repository contains the tokenizer, prompt encoding reference, and a
minimal PyTorch inference implementation for DeepSeek-V4 Flash Vision. The
reference inference covers the vision encoder and aligner, DFlash attention,
MoE, Hyper-Connections, and the DSpark forward path.
...
Repository: localaiLicense: mit
qwopus3.8-27b-flash
Qwopus3.8-27B-Flash is a Qwen3.8-27B fine-tune for reasoning and agent
workloads. This Q4_K_M GGUF includes the F32 vision projector and uses
llama.cpp's embedded chat template with MTP speculative decoding.
The publisher reports a known Python code indentation issue.
Repository: localaiLicense: apache-2.0
qwopus3.8-27b-flash-q8
Qwopus3.8-27B-Flash is a Qwen3.8-27B fine-tune for reasoning and agent
workloads. This Q8_0 GGUF includes the F32 vision projector and uses
llama.cpp's embedded chat template with MTP speculative decoding.
The publisher reports a known Python code indentation issue.
Repository: localaiLicense: apache-2.0
glm-5.3-flash
# GLM-5.3-Flash
👋 Join our WeChat or Discord community.
📖 Check out the GLM-5.3-Flash blog and GLM-5 Technical report.
📍 Use GLM-5.3-Flash API services on Z.ai API Platform.
## Introduction
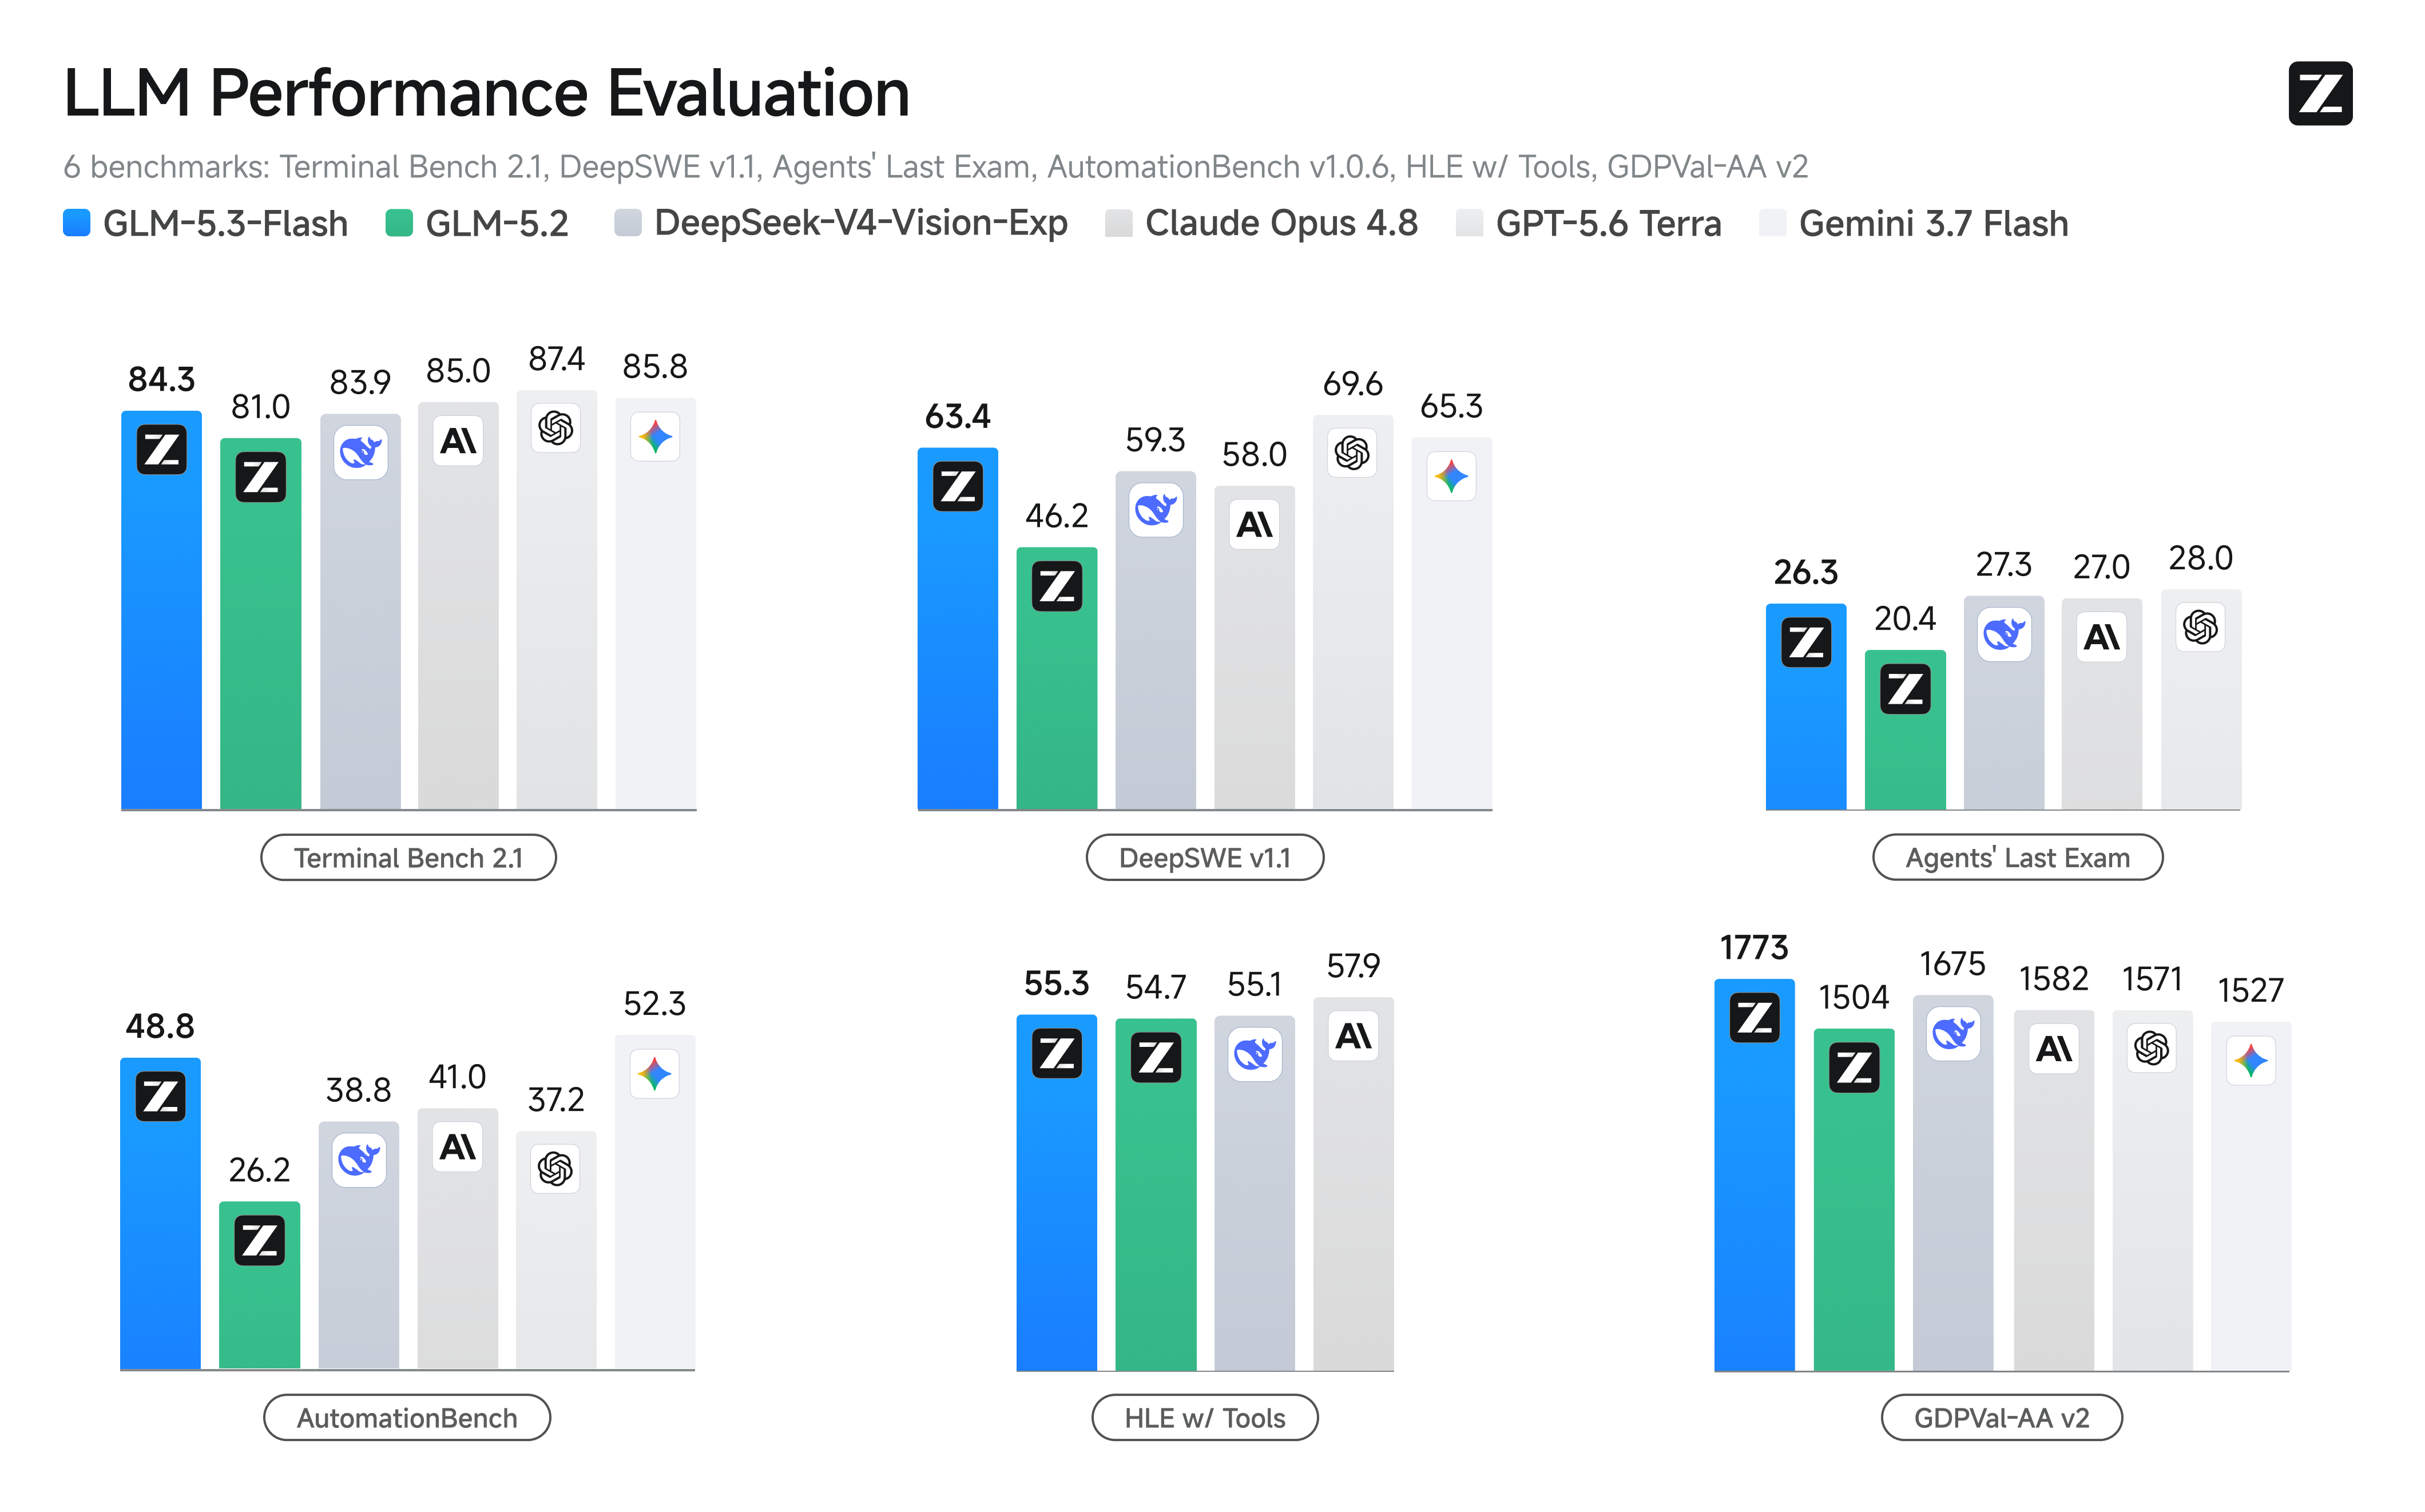
We introduce GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series. With 320B total parameters and just 18B active parameters, it outperforms GLM-5.2 across benchmarks and real-world workloads at one-tenth the price, while approaching Claude Opus 4.8 on coding and agentic benchmarks.
GLM-5.3-Flash starts from a newly trained base model, with its architecture and training recipe redesigned around capability and efficiency. For the first time in the GLM series, we introduce a hybrid architecture combining sparse and linear attention, sharply reducing long-context serving costs while preserving precise long-context capabilities. The model also adopts Manifold-Constrained Hyper-Connections (mHC) to further improve scaling efficiency. Together with our latest 30T-token multimodal pre-training corpus, these changes enable GLM-5.3-Flash to deliver more intelligence with less compute.
## Serve GLM-5.3-Flash Locally
...
Repository: localaiLicense: mit

glm-5.3-flash-q4
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts
model with 18B active parameters. It combines sparse and linear attention
for coding, agentic work, tool use, vision, and long-context tasks. This
entry uses the UD-Q4_K_XL GGUF quantization and enables the model's MTP
speculative-decoding head.
Repository: localaiLicense: mit
glm-5.3-flash-q8
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts
model with 18B active parameters. It combines sparse and linear attention
for coding, agentic work, tool use, vision, and long-context tasks. This
entry uses the higher-quality Q8_0 GGUF quantization and enables the model's
MTP speculative-decoding head.
Repository: localaiLicense: mit

huihui-qwen3.8-flash-next-abliterated-q4
Huihui's abliterated Qwen3.8-Flash-Next is a vision-language
mixture-of-experts model modified to reduce refusals. This entry uses
the publisher's UD-Q4_K_XL GGUF and BF16 vision projector for text chat
and image input through llama.cpp. The default context is 32,768 tokens.
Model weights use the Qwen Community License 1.0.
Repository: localaiLicense: other
qwen3.8-flash-next-q4
Qwen3.8-Flash-Next is Qwen's 125B-parameter, 6B-active experimental
vision-language mixture-of-experts model. It targets agentic coding,
reasoning, tool use, and long-context workloads with a native 262K-token
context window.
This default entry uses Unsloth's UD-Q4_K_XL GGUF and BF16 vision
projector. Linked variants offer Q8_0 and AtomicChat's smaller IQ4_XS
and Q4_K_M builds with a separate n-gram table shard.
Repository: localaiLicense: other
qwen3.8-flash-next-q8
Qwen3.8-Flash-Next in the higher-quality Q8_0 GGUF format, with the shared
BF16 vision projector. This build preserves more model quality but needs
more memory than the default Q4 variant.
Repository: localaiLicense: other
qwen3.8-flash-next-atomic-iq4
Qwen3.8 Flash Next in AtomicChat's AD-3.84bpw IQ4_XS M64 GGUF
build, with the F16 vision projector. The n-gram table occupies a
separate shard. This entry enables memory mapping and disables llama.cpp
automatic parameter fitting as required by the publisher.
Repository: localaiLicense: other
qwen3.8-flash-next-atomic-q4
Qwen3.8 Flash Next in AtomicChat's AD-4.27bpw Q4_K_M M64 GGUF
build, with the F16 vision projector. The n-gram table occupies a
separate shard. This entry enables memory mapping and disables llama.cpp
automatic parameter fitting as required by the publisher.
Repository: localaiLicense: other
qwen3.8-27b-dflash2
# Qwen3.8-27B
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.
> [!Tip]
> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud.
> In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates.
Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date.
...
Repository: localaiLicense: apache-2.0

ling-3.0-flash-iq1
Ling-3.0-flash is InclusionAI's MIT-licensed hybrid reasoning MoE model
with 124B total parameters and 5.5B active parameters per token. It targets
coding, deep research, instruction following, and agentic workflows with a
native 256K-token context window.
This default entry uses the 36.5 GB AD-IQ1_M GGUF. A higher-quality
44.7 GB AD-IQ2_XS model is available as a variant.
Repository: localaiLicense: mit
ling-3.0-flash-iq2
Ling-3.0-flash in the higher-quality 44.7 GB AD-IQ2_XS GGUF format. This
variant preserves more model fidelity for hosts with enough memory.
Repository: localaiLicense: mit
muse-glimmer-30b-dflash
Muse Glimmer's higher-quality dynamic K-quant GGUF with the official
quantized perception encoder and DFlash drafter. DFlash proposes blocks of
up to 16 tokens for the target to verify in parallel, accelerating output
without changing model quality. Flash attention is enabled for this path.
Repository: localaiLicense: apache-2.0
muse-glimmer-30b-17gb-dflash
Muse Glimmer's smaller 17 GB K-quant GGUF with the official quantized
perception encoder and DFlash drafter. This is the lowest-memory published
build that retains image understanding and block-speculative decoding.
Flash attention is enabled for the DFlash path.
Repository: localaiLicense: apache-2.0
deepseek-v4-flash-0731
# DeepSeek-V4-Flash-0731
Technical Report👁️
## Introduction
**DeepSeek-V4-Flash-0731** is the official release of **DeepSeek-V4-Flash**, superseding the preview version, with substantially enhanced agentic capabilities. It has the same model structure as DeepSeek-V4-Flash-DSpark, i.e. it comes with a speculative decoding module attached.
DeepSeek-V4-Flash-0731 outperforms DeepSeek-V4-Pro (Preview) on benchmarks listed below despite its far smaller activated parameter count, and is broadly competitive with the strongest proprietary models available.
Notes:
1. For the Code Agent tasks among the public benchmarks above, DeepSeek-V4-Flash-0731 is evaluated with the minimal mode of DeepSeek Harness (to be released) as the agent framework, using the `max` reasoning effort level with `temperature = 1.0, top_p = 0.95`.
2. † DSBench-FullStack is an internal full-stack development test set; DSBench-Hard is an internal test set of difficult coding-agent problems.
## Chat Template
...
Repository: localaiLicense: mit
deepseek-v4-flash
# DeepSeek-V4: Towards Highly Efficient Million-Token Context Intelligence
Technical Report👁️
## Introduction
We present a preview version of **DeepSeek-V4** series, including two strong Mixture-of-Experts (MoE) language models — **DeepSeek-V4-Pro** with 1.6T parameters (49B activated) and **DeepSeek-V4-Flash** with 284B parameters (13B activated) — both supporting a context length of **one million tokens**.
DeepSeek-V4 series incorporate several key upgrades in architecture and optimization:
1. **Hybrid Attention Architecture:** We design a hybrid attention mechanism combining Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA) to dramatically improve long-context efficiency. In the 1M-token context setting, DeepSeek-V4-Pro requires only **27% of single-token inference FLOPs** and **10% of KV cache** compared with DeepSeek-V3.2.
2. **Manifold-Constrained Hyper-Connections (mHC):** We incorporate mHC to strengthen conventional residual connections, enhancing stability of signal propagation across layers while preserving model expressivity.
3. **Muon Optimizer:** We employ the Muon optimizer for faster convergence and greater training stability.
...
Repository: localaiLicense: mit

laguna-s-2.1-dflash
Laguna S 2.1's 96 GB Q4_K_M target paired with Poolside's 2.2 GB BF16 DFlash drafter for speculative decoding. DFlash drafts a block of tokens per forward pass and accelerates generation without changing the target model's outputs. Flash attention is enabled because the DFlash path requires it.
License: OpenMDW 1.1.
Repository: localaiLicense: other
qwen3-4b-dflash
Qwen3-4B paired with its DFlash block-diffusion drafter for speculative decoding on the llama.cpp backend. This is the canonical DFlash pairing documented upstream (`z-lab/Qwen3-4B-DFlash` + `Qwen/Qwen3-4B`).
DFlash produces a whole block of draft tokens in a single forward pass and injects the target model's hidden states into the drafter's attention, which keeps the drafter tiny while making drafting GPU-friendly. The Q4_K_M file carries the full Qwen3-4B target; the ~0.5 GB Q8_0 drafter (`draft-dflash`) accelerates generation without changing the target's outputs. The drafter is not a standalone chat model: it only runs paired with the target, which is why both are bundled here.
Flash attention is required for DFlash and is enabled in this config. A GPU is recommended.
License: Apache 2.0 (Qwen3-4B target) / MIT (z-lab DFlash drafter).
Repository: localaiLicense: apache-2.0
Page 1