Model Gallery

110 models from 1 repositories

Filter by type:

Filter by tags:
spark-x2.5-4b
# Spark-X2.5 [](https://join.slack.com/t/tokenspark/shared_invite/zt-432qf8l2f-5~dLyXv8uETr0P0UuC07nw) [](https://discord.gg/kTDE2Hg8aw) [](https://www.youtube.com/@SparkLLM) [](https://dev.to/sparkllm) [](https://bsky.app/profile/sparkllm.bsky.social) [](https://x.com/sparkllm) [](https://www.zhihu.com/people/zhiikz7qh7m) [](images/xhtoken-wechat.jpg) > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. ## Introduction We are introducing Spark-X2.5-4B and Spark-X2.5-1.7B, two compact, general-purpose language models designed to make capable AI more practical, efficient, and accessible. The models deliver strong performance across a broad range of everyday tasks—including conversation, writing, translation, reasoning, coding, tool use, and agentic workflows—achieving leading results among open-source models of comparable size. Spark-X2.5 combines an efficiency-oriented architecture with native context windows of up to 1M tokens, and support for more than 200 languages. ...

Repository: localaiLicense: apache-2.0
qwen3.8-flash-next-uncensored
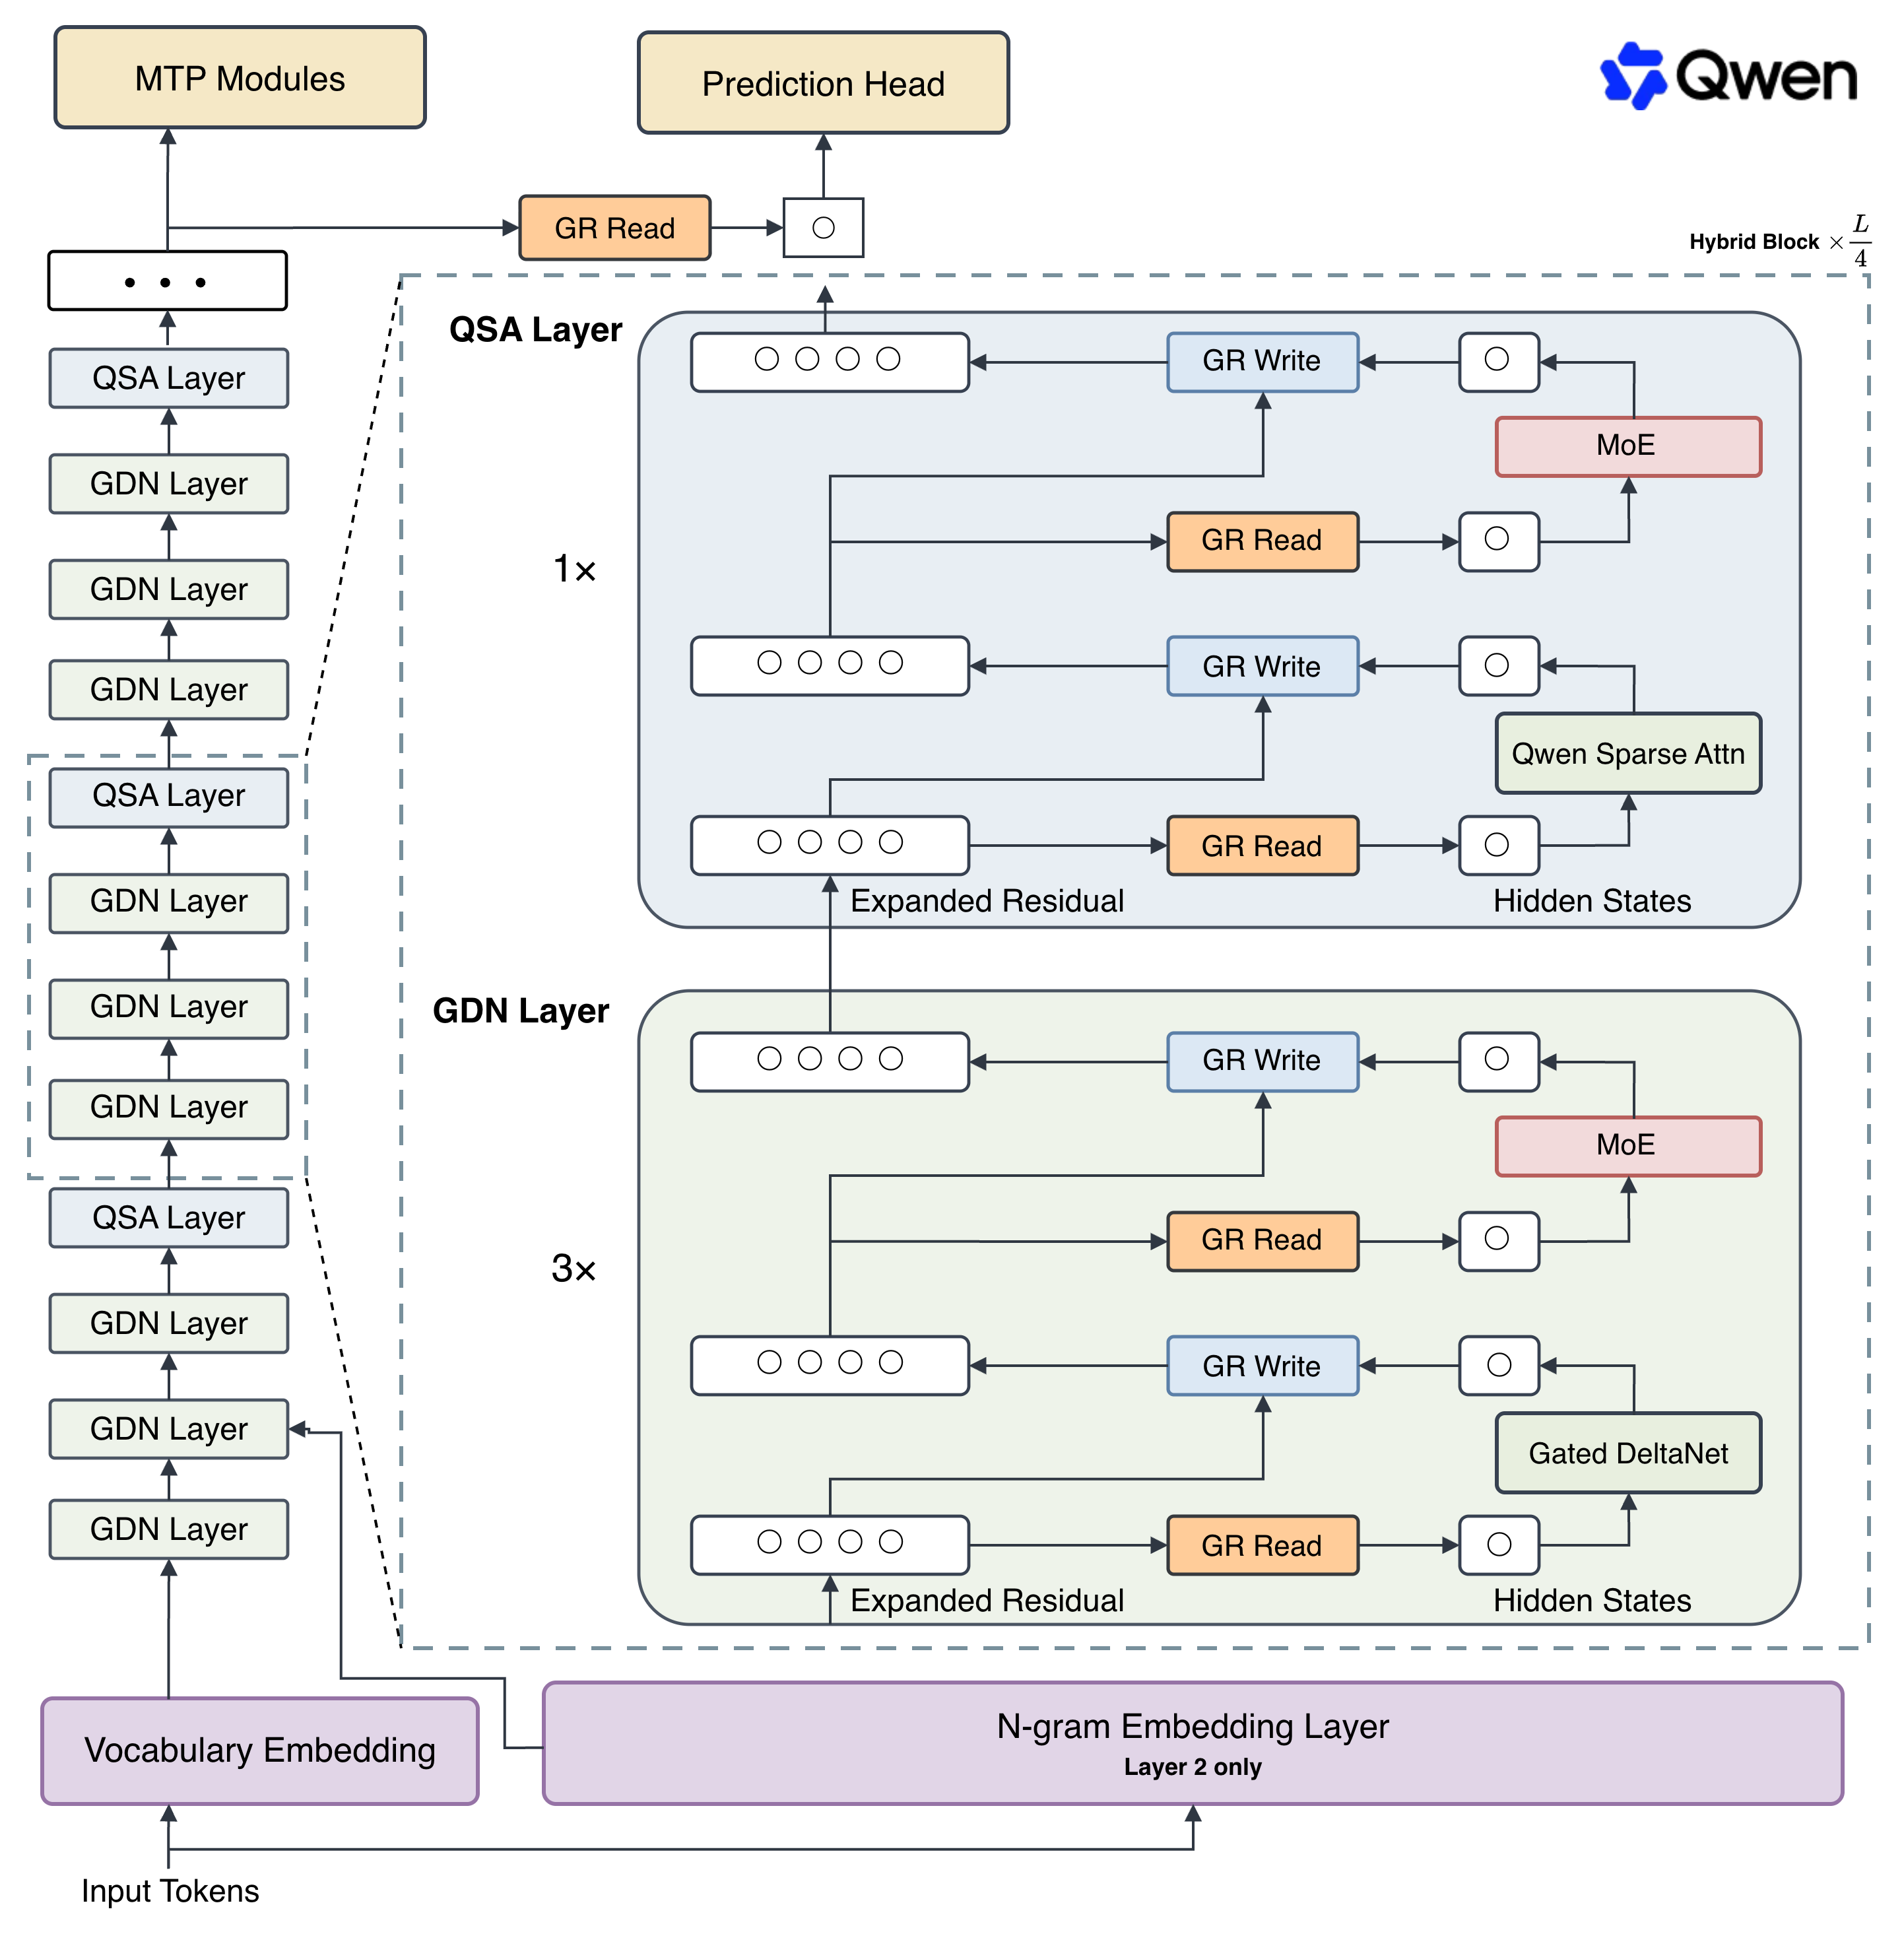
# Qwen3.8-Flash-Next > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > > In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview. As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. ...

Repository: localaiLicense: apache-2.0

ornith-1.0-9b-mtp
[](https://deep-reinforce.com/ornith.html) # Ornith-1.0-9B Aloha! 🌺 Today, we are releasing Ornith-1.0, a self-improving family of open-source models for agentic coding. Highlights: - **State-of-the-Art Coding Agents**: Available in 9B-Dense, 31B-Dense, 35B-MoE, and 397B-MoE (post-trained on top of Gemma 4 and Qwen 3.5), achieving state-of-the-art performance among open-source models of comparable size on coding benchmarks such as Terminal-Bench 2.1, SWE-Bench, NL2Repo and OpenClaw. - **Self-Improving Training Framework**:  Ornith-1.0 employs RL to learn to generate not only solution rollouts, but also the scallfold that drive those rollouts. By jointly optimizing the scaffold and the resulting solution, the model discovers better search trajectories and generates higher-quality solutions. - **Licence**: MIT licensed, globally accessible, and free from regional limitations. ## Ornith 1.0 9B This model card documents **Ornith-1.0-9B**, the most lightweight member of the Ornith family, designed for efficient single-GPU deployment. ### Benchmarks Ornith-1.0-9B Qwen3.5-9B Qwen3.5-35B Gemma4-12B Gemma4-31B Agentic Coding ...

Repository: localaiLicense: mit

ornith-1.0-9b
[](https://deep-reinforce.com/ornith.html) # Ornith-1.0-9B-GGUF Aloha! 🌺 Today, we are releasing Ornith-1.0, a self-improving family of open-source models for agentic coding. Highlights: - **State-of-the-Art Coding Agents**: Available in 9B-Dense, 31B-Dense, 35B-MoE, and 397B-MoE (post-trained on top of Gemma 4 and Qwen 3.5), achieving state-of-the-art performance among open-source models of comparable size on coding benchmarks such as Terminal-Bench 2.1, SWE-Bench, NL2Repo and OpenClaw. - **Self-Improving Training Framework**:  Ornith-1.0 employs RL to learn to generate not only solution rollouts, but also the scallfold that drive those rollouts. By jointly optimizing the scaffold and the resulting solution, the model discovers better search trajectories and generates higher-quality solutions. - **Licence**: MIT licensed, globally accessible, and free from regional limitations. ## Ornith 1.0 9B This model card documents **Ornith-1.0-9B**, the most lightweight member of the Ornith family, designed for efficient single-GPU deployment. ### Benchmarks Ornith-1.0-9B Qwen3.5-9B Qwen3.5-35B Gemma4-12B Gemma4-31B Agentic Coding ...

Repository: localaiLicense: mit

ornith-1.0-35b
[](https://deep-reinforce.com/ornith.html) # Ornith-1.0-35B-GGUF Aloha! 🌺 Today, we are releasing Ornith-1.0, a self-improving family of open-source models for agentic coding. Highlights: - **State-of-the-Art Coding Agents**: Available in 9B-Dense, 31B-Dense, 35B-MoE, and 397B-MoE (post-trained on top of Gemma 4 and Qwen 3.5), achieving state-of-the-art performance among open-source models of comparable size on coding benchmarks such as Terminal-Bench 2.1, SWE-Bench, NL2Repo and OpenClaw. - **Self-Improving Training Framework**: Ornith-1.0 employs RL to learn to generate not only solution rollouts, but also the scallfold that drive those rollouts. By jointly optimizing the scaffold and the resulting solution, the model discovers better search trajectories and generates higher-quality solutions. - **Licence**: MIT licensed, globally accessible, and free from regional limitations. ## Ornith 1.0 35B This model card documents **Ornith-1.0-35B**, the lightweight member of the Ornith family, designed for efficient single-GPU deployment. ### Benchmarks Ornith-1.0-35B Qwen3.5-35B Qwen3.6-35B Gemma4-31B Qwen3.5-397B Agentic Coding ...

Repository: localaiLicense: mit

qwopus3.5-9b-coder-mtp
# 🌟 Qwopus3.5-9B-v3.5 ## 💡 Model Overview & v3.5 Design Qwopus3.5-9B-v3.5 is a **data-scaled continuation** of the Qwopus3.5-9B-v3 model. The training data in v3.5 is expanded to cover a broader range of domains, including mathematics, programming, puzzle-solving, multilingual dialogue, instruction-following, multi-turn interactions, and STEM-related tasks. Qwopus3.5-9B-v3.5 is a reasoning-enhanced model based on **Qwen3.5-9B**, designed for: - 🧩 Structured reasoning - 🔧 Tool-augmented workflows - 🔁 Multi-step agentic tasks - ⚡ Token-efficient inference Compared with Qwopus3.5-9B-v3, **3.5 version does not introduce a new architecture, RL stage, or template redesign**. This version is trained with approximately **2× more SFT data**. ## 🎯 Motivation & Generalization Insight The motivation behind v3.5 comes from a simple observation: > This work is motivated by the hypothesis that scaling high-quality SFT data may further enhance the generalization ability of large language models. In earlier Qwopus3.5 experiments, structured reasoning was observed to improve both **accuracy and efficiency**: ...

Repository: localaiLicense: apache-2.0

gemma-4-26b-a4b-it
Google Gemma 4 26B-A4B-IT is an open-source multimodal Mixture-of-Experts model with 26B total parameters and 4B active parameters. It handles text and image input, generating text output, with a 256K context window and support for 140+ languages. The MoE architecture provides strong performance with efficient inference. Well-suited for question answering, summarization, reasoning, and image understanding tasks.

Repository: localaiLicense: apache-2.0
gemma-4-e2b-it
Google Gemma 4 E2B-IT is a lightweight open-source multimodal model with 5B total parameters and 2B effective parameters using selective parameter activation. It handles text and image input, generating text output, with a 256K context window and support for 140+ languages. Optimized for efficient execution on low-resource devices including mobile and laptops.

Repository: localaiLicense: apache-2.0
qwen_qwen3.5-2b
Qwen3.5-2B is a highly efficient, instruction-tuned multilingual language model available in various quantized GGUF formats. Optimized for llama-cpp inference, it supports chat and completion tasks with strong performance on low-RAM hardware. The model is available in multiple quantization levels ranging from Q8_0 to IQ2_M to balance quality and resource usage.

Repository: localaiLicense: apache-2.0

qwen_qwen3.5-4b
Qwen3.5-4B is a multimodal LLM with 4 billion parameters, optimized for chat and vision tasks. This GGUF quantized version enables efficient local inference via llama-cpp backend. Supports both text and image input for enhanced conversational capabilities.

Repository: localaiLicense: apache-2.0
voxtral-mini-4b-realtime
Voxtral Mini 4B Realtime is a speech-to-text model from Mistral AI. It is a 4B parameter model optimized for fast, accurate audio transcription with low latency, making it ideal for real-time applications. The model uses the Voxtral architecture for efficient audio processing.

Repository: localaiLicense: apache-2.0

moonshine-tiny
Moonshine Tiny is a lightweight speech-to-text model optimized for fast transcription. It is designed for efficient on-device ASR with high accuracy relative to its size.

Repository: localaiLicense: apache-2.0

omnilingual-0.3b-ctc-q8-sherpa
Omnilingual ASR CTC 300M (int8) is a multilingual automatic speech recognition model supporting 1,600+ languages. Based on Meta's omniASR_CTC_300M architecture (Wav2Vec2 with CTC head), quantized to int8 for efficient inference. Uses the sherpa-onnx backend with ONNX Runtime.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-efficientthink-q6
Qwen3.8-27B EfficientThink, a reasoning fine-tune by nerkyor, in Q6_K GGUF format with the matching Q8 vision projector.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-efficientthink-q8
Qwen3.8-27B EfficientThink, a reasoning fine-tune by nerkyor, in Q8_0 GGUF format with the matching Q8 vision projector.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-efficientthink-q6-dflash
Qwen3.8-27B EfficientThink, a reasoning fine-tune by nerkyor, in Q6_K GGUF format with the matching Q8 vision projector. Enables DFlash speculative decoding with the publisher's Q8 draft.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-efficientthink-q8-dflash
Qwen3.8-27B EfficientThink, a reasoning fine-tune by nerkyor, in Q8_0 GGUF format with the matching Q8 vision projector. Enables DFlash speculative decoding with the publisher's Q8 draft.

Repository: localaiLicense: apache-2.0

deepseek-ai.deepseek-v3.2
This is a quantized version of the DeepSeek-V3.2 model by deepseek-ai, optimized for efficient deployment. It is designed for text generation tasks and supports the pipeline tag `text-generation`. The model is based on the original DeepSeek-V3.2 architecture and is available for use in various applications. For more details, refer to the [official repository](https://github.com/DevQuasar/deepseek-ai.DeepSeek-V3.2-GGUF).

Repository: localai

mox-small-1-i1
The model, **vanta-research/mox-small-1**, is a small-scale text-generation model optimized for conversational AI tasks. It supports chat, persona research, and chatbot applications. The quantized versions (e.g., i1-Q4_K_M, i1-Q4_K_S) are available for efficient deployment, with the i1-Q4_K_S variant offering the best balance of size, speed, and quality. The model is designed for lightweight inference and is compatible with frameworks like HuggingFace Transformers.

Repository: localaiLicense: apache-2.0

glm-4.7-flash
**GLM-4.7-Flash** is a 30B-A3B MoE (Model Organism Ensemble) model designed for efficient deployment. It outperforms competitors in benchmarks like AIME 25, GPQA, and τ²-Bench, offering strong accuracy while balancing performance and efficiency. Optimized for lightweight use cases, it supports inference via frameworks like vLLM and SGLang, with detailed deployment instructions in the official repository. Ideal for applications requiring high-quality text generation with minimal resource consumption.

Repository: localaiLicense: mit

iquest-coder-v1-40b-instruct-i1
The **IQuest-Coder-V1-40B-Instruct-i1-GGUF** is a quantized version of the original **IQuestLab/IQuest-Coder-V1-40B-Instruct** model, designed for efficient deployment. It is an **instruction-following large language model** with 40 billion parameters, optimized for tasks like code generation and reasoning. **Key Features:** - **Size:** 40B parameters (quantized for efficiency). - **Purpose:** Instruction-based coding and reasoning. - **Format:** GGUF (supports multi-part files). - **Quantization:** Uses advanced techniques (e.g., IQ3_M, Q4_K_M) for balance between performance and quality. **Available Quantizations:** - Optimized for speed and size: **i1-Q4_K_M** (recommended). - Lower-quality options for trade-off between size/quality. **Note:** This is a **quantized version** of the original model, but the base model (IQuestLab/IQuest-Coder-V1-40B-Instruct) is the official source. For full functionality, use the unquantized version or verify compatibility with your deployment tools.

Repository: localaiLicense: iquestcoder

Page 1